CIA Brief 20261114

image

Security

Microsoft 365 & Windows

  • Microsoft’s attempts to resolve major outage ‘not working as expected’
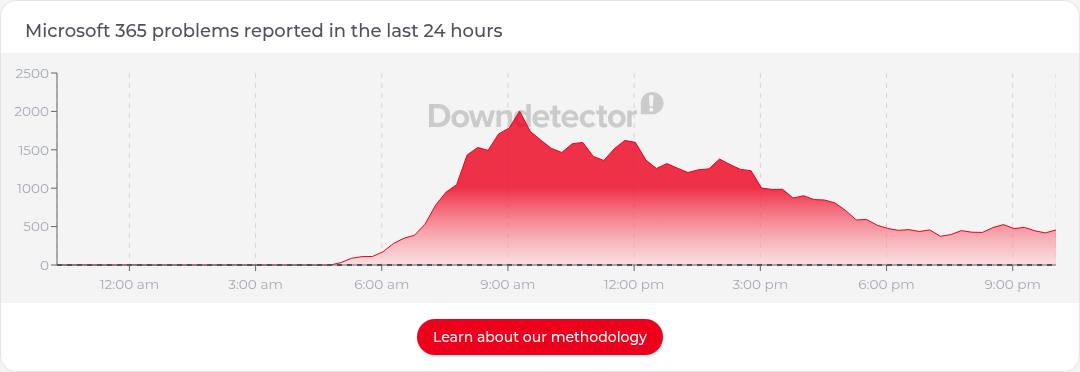
    Friday’s Microsoft 365 outage hit Outlook hardest from about 5am Sydney time, with Downdetector peaking near 20,000 reports a minute across 74 countries. Teams mostly kept working while mail stayed patchy well into the evening. Good reminder to have a client communication plan and an out-of-band contact channel ready before the next big outage.
    https://www.smh.com.au/technology/microsoft-hit-by-widespread-outage-20261113-p61duy.html
  • How I used Grok Bot to watch the 13 November 2026 Microsoft 365 outage
    My write-up of how I used Grok Bot to track Friday’s outage as it happened, pulling together Microsoft’s status updates, @MSFT365Status and Downdetector into one running timeline. It covers what broke (mostly anything that touched Exchange Online), what kept working, and where Microsoft missed a scheduled update. Useful if you want to automate outage monitoring for your clients.
    https://blog.ciaops.com/2026/11/14/how-i-used-grok-bot-to-watch-the-13-november-2026-microsoft-365-outage/
  • CIAOPS Microsoft 365 Outage Status
    I’ve set up a public page that summarises major Microsoft 365 outages in plain English, with times in Sydney time. Grok Bot updates it automatically from Microsoft’s service status, @MSFT365Status and Downdetector Australia. Bookmark it and share it with clients who can’t see the admin centre health dashboard.
    https://blog.ciaops.com/m365-outage-status/
  • MC1546354 – Discover usage-based billing (UBB) experiences like Cowork, Code, and Autopilot
    Users with a Microsoft 365 Copilot licence will see entry points for usage-based billing experiences like Cowork, Code and Autopilot even if the tenant hasn’t enabled them, with an option to request access. A new admin setting arrives mid-November, a custom ‘Learn more’ URL option in mid-December, and enforcement at the end of January 2027 (end of February for deferred release). Only Copilot-licensed tenants are affected, but set the policy now or expect requests your clients didn’t budget for.
    https://mc.merill.net/message/MC1546354
  • Microsoft Copilot Connectors Update: October 2026
    Copilot connectors now sit in one catalogue across Copilot Chat, Word, Excel, PowerPoint and Researcher. There are new connectors (Trello Enterprise, Galileo and 25+ healthcare and life sciences sources), connector ‘skills’ starting with HubSpot and Notion, and richer Salesforce, ServiceNow and Confluence answers. Copilot gets more useful when it can reach the systems your clients already use, so it’s worth reviewing.
    https://techcommunity.microsoft.com/blog/microsoft-copilot-blog/microsoft-copilot-connectors-update-october-2026/4572240
  • Available today: Anthropic Claude Fable 5.2 in Microsoft Copilot
    Claude Fable 5.2 is rolling out in Copilot Cowork and Copilot Studio, grounded in tenant files, meetings and chats through Work IQ within existing permissions. More model choice is good, but it also means more decisions about which model to use for which job. Check whether Anthropic models are enabled in your clients’ tenants before people go looking for it.
    https://techcommunity.microsoft.com/blog/microsoft-copilot-blog/available-today-anthropic-claude-fable-5-2-in-microsoft-copilot/4571829
  • We have a new LLM in Copilot winner: Opus 5.5 edges Fable 5.2
    My latest head-to-head of the models in Copilot Cowork. Fable 5.2 beat Fable 5.1, but Opus 5.5 still edged it 8.9 to 8.6, mainly on evidence and detail. Fable 5.2 was the more polished, executive-friendly read. If you’re choosing a default model for research-style work, the comparison and outputs are all linked.
    https://blog.ciaops.com/2026/11/13/we-have-a-new-llm-in-copilot-winner-opus-5-5-edges-fable-5-2/
  • Use connected financial intelligence with Copilot in real financial workflows
    Microsoft shows Copilot connectors bringing specialist financial research and data into Copilot alongside a firm’s own files and conversations through Work IQ, for jobs like credit briefings and client reviews. People still sign off on the recommendations and decisions. Nothing groundbreaking, but it’s a useful pattern if you support accounting or advisory clients.
    https://techcommunity.microsoft.com/blog/microsoft-copilot-blog/use-connected-financial-intelligence-with-copilot-in-real-financial-workflows/4571099

Cloud & AI

Other

After hours

Watch Starship’s First DOUBLE CATCH!!! – https://www.youtube.com/watch?v=QJFdKoKNn2M

Editorial

If you found this valuable, the I’d appreciate a ‘like’ or perhaps a donation at https://ko-fi.com/ciaops. This helps me know that people enjoy what I have created and provides resources to allow me to create more content. If you have any feedback or suggestions around this, I’m all ears. You can also find me via email director@ciaops.com and on X (Twitter) at https://www.twitter.com/directorcia.

If you want to be part of a dedicated Microsoft Cloud community with information and interactions daily, then consider becoming a CIAOPS Patron – www.ciaopspatron.com.

Watch out for the next CIA Brief next week
How Grok Bot Can Watch Microsoft 365 Status and Alert You When Something Breaks

Two colleagues reviewing a laptop in a quietly lit office at dawn, teal and amber light on a blank screen

The first person to tell an MSP about a Microsoft 365 outage should not be the client who cannot open Outlook. I would rather a Grok Bot routine check status.cloud.microsoft for me, tell me when Microsoft posts an incident, keep watching while it is open, and tell me when it is marked restored. If customers might be affected, I want the same bot to draft a notice I can approve. It should not send anything on its own.

That is the whole job. Grok Bot is the monitor. The public status page is the source. A routine is the schedule. Everything else in this post – the admin centre Service health page, and the Graph API behind it – is useful context for later. It is not the starting point.

I am writing this on Friday, 13 November 2026, in Sydney. While I was putting the post together, the public page was already showing a service degradation: users may be unable to connect to multiple Microsoft 365 services, including Exchange Online, Microsoft Teams, SharePoint Online and Microsoft 365 Copilot. Microsoft had posted a current status, a previous status, and a time for the next update. That is exactly the sort of event I want Grok Bot to catch and stay with, rather than me discovering it in a ticket queue.

What Grok Bot is actually watching

Microsoft documents the public service status page as the place to check when you cannot sign in to the admin centre. The official write-up is How to check Microsoft 365 service health. The page is unauthenticated, so a Grok Bot routine can fetch it without a tenant sign-in. That is the point. If the admin centre itself is hard to reach, you still have a public source.

The site is a status page, not a full history. I checked what it actually exposes, rather than inventing an API. The page’s own code loads a current Microsoft 365 post from https://status.cloud.microsoft/api/posts/mac, and it publishes the same item as RSS at https://status.cloud.microsoft/api/feed/mac. There is a matching Power Platform feed at /api/feed/ppac, and the page points at Microsoft’s Azure status RSS for Azure. The Microsoft 365 post I fetched included a title, a status such as “Service degradation” or “Service restored”, timestamps, and a message with user impact, the current status, earlier updates, and a “Next update by” time. That is enough for a bot to notice a new incident, see whether the wording has changed, and notice when the status returns to available or restored.

One practical detail is worth knowing. The public page itself refreshes those posts on a five-minute interval. That is in the page’s own code. It is not a published Microsoft SLA for how quickly an update will appear. Microsoft often says when the next update is due inside the post. Grok Bot should treat that time as a promise to check against, not as a guarantee.

The public page is also broad. It tells you about a widespread issue Microsoft has chosen to post there. It does not tell you whether a particular tenant is affected, and it will not list the quieter advisories that show up in a tenant’s own Service health view. I will come back to that difference later. For the first routine, the public page is the right source because Grok Bot can read it with no extra permissions.

Set up a Grok Bot routine to watch and alert

You can do this on a dedicated status bot, or add the routine to a bot you already use for monitoring. I already use Grok Bot routines for a morning news brief, which I walked through in How to Use Grok Bot to Monitor MSP News and Security Updates. This is the same idea, pointed at one official page.

The app locations I will point you to are ones I have verified. Click the agent’s name in the chat header, or use Cmd+Shift+I, to open the per-agent info pane. Saved routines sit in that pane, under the computer preview. Check the timezone under Settings, on the General tab, opened from the sidebar account button at the bottom-left, or with Cmd+,. If you want the bot named and described clearly, the gear beside the X in the info pane opens the per-agent settings for avatar, name, title and description.

Create the routine in chat. Routines usually start within a few minutes either side of the time you set. If the run must start right on the minute, say “exactly” or “sharp”.

Here is the prompt I would use:

Create a routine called Microsoft 365 public status watch. Every 15 minutes during my Sydney business hours, check https://status.cloud.microsoft/ and the Microsoft 365 RSS feed at https://status.cloud.microsoft/api/feed/mac. You can also read the current post at https://status.cloud.microsoft/api/posts/mac.

Compare the current title, status and message with what you saw on the last run. If nothing material has changed, stay silent.

If a new incident or service degradation is posted, or if the status, title or message has changed, post an alert in this chat. Include:
- the title and current status
- the affected services, in plain English
- the current update, and what changed since last time
- the "Next update by" time, converted to Sydney time
- a link to https://status.cloud.microsoft/

Do not invent endpoints or details that are not on the page or in the feed. Do not sign in to a tenant for this routine. Do not email or message anyone else. If the page cannot be reached, say so once and try again on the next run.

Fifteen minutes is a starting cadence, not a law. The page is already checking about every five minutes, so you can tighten the routine if you want it closer to that. Outside business hours you might run it less often, then keep a closer watch once an incident is open. What matters is that Grok Bot compares each run with the last one, and only speaks when something has changed.

Keep watching during the outage

An alert is only the start. Once Microsoft has posted an incident, I want Grok Bot to stay with it. The useful work is noticing what changed in the update, not repeating the same paragraph every quarter of an hour.

Ask it, in the same chat, to tighten the watch for as long as the incident is open. I would tell it to check again at or just after the “Next update by” time, and otherwise on a short interval, and to report only when the current status text, the list of affected services, or the overall status has changed. If Microsoft slips past the promised update time with no new post, I want the bot to say that too.

A during-outage prompt looks like this:

An incident is open on https://status.cloud.microsoft/. Until the status is Service restored or Available, watch it more closely. Check the current Microsoft 365 post and RSS feed at least every five minutes, and again at the "Next update by" time Microsoft has published, in Sydney time.

Only message me when something has changed: the status, the title, the list of affected services, or the current status text. Quote the new current status in a few lines, say what changed since the last update, and give the next promised update time. If that time passes with no new post, tell me once. Do not notify customers. Do not invent progress that Microsoft has not posted.

That is also how I would have wanted it to behave this morning. The public post already had a current status and a previous status in the same message. A bot that only looks at a timestamp can miss a wording change. Compare the text.

Report when it is resolved

When Microsoft marks the issue as restored, I want a short all-clear in the same chat: what was affected, when it started, when it was restored, and a reminder that the public page is a broad signal, not proof that every tenant is back to normal. Then the routine can go back to staying quiet.

The resolution prompt:

If https://status.cloud.microsoft/ marks the current Microsoft 365 incident as Service restored or Available, post a resolution report in this chat and then return to the quieter watch. Include the original title, the services that were listed as affected, when the issue was first posted, when it was marked restored, and a short timeline of the updates you saw. Say clearly that this is the public status, not a tenant-by-tenant confirmation. Do not send any customer message unless I ask you to draft one.

Draft the customer notice, then wait for approval

This is where the same Grok Bot work becomes useful for an MSP. If Exchange Online, Teams, SharePoint or Outlook might be affected, customers will ask. I would rather answer from Microsoft’s own words, in a calm note I have actually read, than type one under pressure.

The important rule is that Grok Bot drafts, and you send. Do not let the routine email clients, post to a Teams channel, or update a status page on its own. Leave the draft in the chat. You decide whether the incident is material enough to mention, whether the wording is right, and when it goes out. The same applies to the all-clear.

A prompt for that draft:

Draft a short customer notice, in plain English, based only on the current public incident at https://status.cloud.microsoft/. Write it as an MSP note I can send if I choose to. Include what Microsoft says may be affected, that Microsoft is working on it, a link to the public status page, and that we will follow up when the status is restored. Keep it factual. Do not claim we have confirmed impact in the customer's tenant. Do not apologise for a fault we did not cause, and do not guess at a resolution time.

Leave the draft in this chat. Do not send it, email it, or post it anywhere. I will approve or edit it first. Also draft a matching all-clear I can use once Microsoft marks the issue restored, and hold that back as well.

If you later want the approved text in Outlook or Teams, you can ask the bot to place a draft where you work. That is a separate, approved step. It is not part of the watch routine.

A deeper option: tenant Service health

The public page is the wide, no-sign-in view. Microsoft’s fuller picture for a given organisation still lives in the Microsoft 365 admin centre, under Health, then Service health, which the same Learn article describes. That view is tenant-specific. It lists incidents and advisories that apply to the services that tenant uses, with an issue ID, a history of updates, and, if you want them, email notifications. Roles such as Service Support admin and Helpdesk admin can see it. Planned maintenance is not in Service health; that sits in Message centre.

The programmable version of that tenant view is the service communications API in Microsoft Graph. The permission for health issues is ServiceHealth.Read.All, as delegated or application access, granted by an administrator. Message centre posts are a different permission. Unattended monitoring is the application-permission path, which Microsoft describes for backend alert services in Access service health and communications in Microsoft Graph.

I already have a Grok Bot doing that deeper check in a tenant security routine. It is not watching the public page. It reads Service health for that tenant and includes it in a morning report. On a typical day it has found a dozen or more unresolved items, mostly advisories – a Copilot agent opening the wrong window, a SharePoint knowledge-agent limitation, an Exchange group-reply problem – rather than a wide outage. That is useful, and it is a different job. The public page would have been quiet on those mornings. The tenant view is noisier and more precise. If you add it, keep the public-page routine as the early, permission-free alert, and treat tenant Service health as the follow-up that answers “is this likely affecting this customer?”

I have also written about using a specialist Grok Bot when something in a tenant already looks wrong, in How Grok Bot Simplifies Security Checks and Investigations. Status monitoring is the earlier step: know that Microsoft has posted an issue before you start digging.

Sample prompts

These are the four prompts together, so you can paste them as you set this up.

Routine setup:

Create a routine called Microsoft 365 public status watch. Every 15 minutes during my Sydney business hours, check https://status.cloud.microsoft/ and https://status.cloud.microsoft/api/feed/mac. Compare the title, status and message with the last run. Stay silent if nothing has changed. If a new incident or service degradation appears, or if the post has changed, alert me in this chat with the title, status, affected services, what changed, the next update time in Sydney time, and a link to the page. Do not invent details. Do not sign in to a tenant. Do not contact customers.

During an outage:

Watch the open incident on https://status.cloud.microsoft/ more closely until it is Service restored or Available. Check at least every five minutes, and at the "Next update by" time. Only message me when the status, title, affected services or current update text changes, or if the promised update time passes with no new post. Do not notify customers.

Resolution report:

When the public Microsoft 365 incident is marked Service restored or Available, post a short resolution report in this chat: original title, affected services, first-posted time, restored time, and a brief timeline. Remind me this is the public status, not a per-tenant confirmation. Then return to the quieter watch. Do not send a customer message unless I ask for a draft.

Customer notice draft:

Draft a short customer notice from the current public incident only. Say what may be affected, that Microsoft is working on it, and link to https://status.cloud.microsoft/. Do not claim confirmed impact in a customer's tenant, and do not guess a resolution time. Leave the draft in this chat. Do not send it. Also prepare an all-clear draft and hold that back until I approve it.

What I want from this

The useful design is a Grok Bot that watches one official public page, speaks when the post changes, stays with the incident, and writes a customer note I still have to approve. It will not replace the admin centre, and it will not tell you with certainty that a given tenant is affected. It will mean you heard about the outage from your own bot, in your own chat, with Microsoft’s wording in front of you, before the first customer call.

How I used Grok Bot to watch the 13 November 2026 Microsoft 365 outage

A paper-cut collage of a quiet desk and a blank monitor

On Friday 13 November 2026, Microsoft 365 had a long, messy day. From around 5am Sydney time, user reports started climbing on Downdetector Australia. Microsoft’s first public status post arrived at 8:01am. After that came partial recoveries, setbacks, a missed 7:30pm update, and a late-evening note that repairs had finished on part of the Asia Pacific infrastructure. Outlook was the service most people felt. Teams calls, meetings and chats mostly kept working. Files in SharePoint and OneDrive still opened. A lot of the pain sat in anything that had to talk to Exchange Online: mailbox access, delayed email, calendars, Copilot, and admin portals.

If you run an MSP, you already know that day. The phones start early. Users want their password reset. Your technicians need to know whether this is a tenant issue or a Microsoft issue, and you need something accurate you can paste to customers.

I already had a Grok Bot I use as a help desk assistant. I had also just written about pointing a routine at Microsoft’s public status page, in How Grok Bot Can Watch Microsoft 365 Status and Alert You When Something Breaks. This post is what happened when that idea met a real Friday outage, and how I set the watch up so you can copy the pattern. By the end of the day it had grown into a scheduled check, a copy-and-paste report, a plain-English section for everyday users, Downdetector charts, and a public WordPress page that updates itself: https://blog.ciaops.com/m365-outage-status/.

Nothing here is a substitute for your own tenant’s Service health view in the Microsoft 365 admin center. This account stops at 10:39pm Sydney time, when I closed the incident on the CIAOPS side. It does not cover anything Microsoft posted overnight after that.

What the 13 November outage looked like from Sydney

These times are Sydney time (AEDT) on Friday 13 November 2026, from Microsoft’s public status posts, @MSFT365Status on X, Downdetector Australia, and the CIAOPS running log. Microsoft tracked the incident as EX1550543 / MO1550821, a service degradation affecting features that depend on Exchange Online. It also listed Teams and SharePoint among the affected services; the sharp end, for most people, was still mail and calendar.

  • About 5:00am: user reports start rising on Downdetector AU.
  • 8:01am: Microsoft’s first status post.
  • 10:06am: some servers back in service and partial recovery in some regions.
  • 11:08am: setback, as servers returned to service stopped responding again under load.
  • 12:06pm: Microsoft said the root cause was an overloaded secure-connection process, and that a configuration fix was being validated, a network change was being reverted, and traffic limits were in effect.
  • Through the afternoon: more capacity work, more setbacks, including a mitigation that caused a surge of internal traffic, and a confirmation that Microsoft had no indication of malicious activity.
  • 7:30pm: the promised update was not posted on time.
  • 8:10pm: early signs of stabilisation, but capacity was not back to normal. Microsoft extended the email timeout window to 48 hours so delayed messages would be held and retried.
  • 9:01pm: a status note only. Incremental improvement, health still variable, no ETA.
  • 10:04pm: recovery actions completed across portions of the affected infrastructure in the Asia Pacific region. Traffic was being gradually restored. Mailbox access and delayed email processing were improving, with intermittent issues remaining.
  • 10:39pm: I told the help desk bot to consider the outage resolved on the CIAOPS side. Microsoft had not yet posted a formal restore. The public page was updated with a closing note at 10:41pm, and the watch stayed on for any genuinely new incident.

Closing it on my side is not the same as Microsoft declaring the incident over. The page said so, and pointed people back to Service health and status.cloud.microsoft for Microsoft’s final confirmation.

How the watch is put together

A scheduled routine wakes the help desk bot about every 15 minutes. The bot reads three public sources, compares them with a small state file, and only then decides whether to alert me, rebuild the customer report, and update the WordPress page.

  1. A routine, not a one-off chat. The watch is a saved prompt on a schedule. A conversation is not enough, because the chat will end and the bot will stop looking.
  2. Microsoft’s public status feed. The bot polls the public JSON endpoints behind https://status.cloud.microsoft/, not a scraped screenshot. In practice that is /api/posts/mac for Microsoft 365, plus /azure and /ppac. The Power Platform feed has a standing “Available” notice that we ignore.
  3. X, but only while an outage is active. The bot uses Grok Bot’s built-in public search for posts from @MSFT365Status. Some posts appear there slightly ahead of, or in addition to, the status page. Many simply repeat it.
  4. Downdetector Australia as an independent signal. Official status and user reports do not always move in lockstep. We treat Downdetector as indicative only, never as proof.
  5. A state file. It stores the last incident id, last update time, a short hash of the message, when the next Microsoft update is due, recent X post ids, and a short Downdetector snapshot. On this day, it was worth comparing the update time and the message body as well as the id, so a new post id was not treated as a brand-new outage on its own.
  6. Charts. A short script on the bot’s computer captures the 24-hour chart from each Downdetector Australia service page.
  7. One WordPress page. The WordPress.com connector updates that page and uploads the new charts. Standing approval is limited to that one page.
  8. Me, in chat, only when it matters. If nothing changed, the routine stays quiet. If Microsoft is more than ten minutes late for a promised update, I get a short overdue note.

The same bot also does remote support through AnyDesk, and it has a dedicated help desk inbox. That is a different routine. I will come back to it at the end.

Step-by-step setup

You can copy this pattern on your own Grok Bot. I built a lot of it during a live incident, which I would not recommend if you can avoid it. Set it up on a quiet day, test it against the current status page, then leave it running.

1. Start with a bot you already trust. I used my help desk bot, because it already had rules about approvals, secrets and Sydney time. You could use a dedicated status bot if you prefer to keep support work separate.

2. Check the timezone, then find routines. Open Settings from the sidebar account button at the bottom-left, or with Cmd+, (or the command palette’s “Open settings”), and check the timezone on the General tab. To see saved routines, click the agent’s name in the chat header, or use Cmd+Shift+I, to open the per-agent info pane. Routines sit in that pane, under the computer preview. You can still create the routine in chat. Routines usually start within a few minutes either side of the time you set. If the run must start right on the minute, say “exactly” or “sharp”.

3. Ask for a watch, not a dashboard. Name the source, what counts as “major”, and what you want when an incident starts and when it ends. Do not ask the bot to email your customers on its own.

4. Add independent sources once the first watch is working. I added @MSFT365Status, then Downdetector Australia, then the charts, then the copy-and-paste report, then the WordPress page. Each add-on was a short instruction, not a redesign.

5. Put the watch on a schedule. I used a 15-minute cadence, in Sydney time: 7, 22, 37 and 52 minutes past each hour, with a little flexibility either side so a slow run does not collide with the next one.

6. Make it keep state. Tell the bot to store what it last saw, and to compare against that file every run. Without this, you get either no history or a repeat of the same alert.

7. Create the public page yourself, then give narrow permission to update it. I created https://blog.ciaops.com/m365-outage-status/ first. The bot is allowed to update that page and upload charts for it. It is not allowed to create a second page, or change any other post, menu or setting.

8. Decide what “resolved” means on your side. Microsoft may keep posting about the same incident after you have stopped actively tracking it. You need a rule for that, or you will get woken up by repeat posts.

In the earlier how-to I said a routine should draft a customer notice and wait, and should not update a status page on its own. That remains the default. What I did on 13 November was a deliberate, written exception for one operational page.

Example prompts you can copy

These are the sorts of instructions I used, cleaned up so you can paste them. They are examples, not a magic script. The earlier ones are reconstructed from the requests I made during the day, because I built the watch in stages rather than from a single perfect brief. The two later ones, about the plain-English section and closing the incident, are close to my original wording.

The initial ask (example, reconstructed):

Watch https://status.cloud.microsoft/ and tell me about major Microsoft 365 outages I need to be aware of, and tell me when those outages are restored. Use Sydney time. If nothing important has changed, don’t message me.

Monitor X while an outage is active (example, reconstructed):

While an outage is active, also monitor @MSFT365Status on X (https://x.com/MSFT365Status) for information that is not already on the status page. Don’t treat a repeat of the same status text as news.

Add Downdetector as an independent check (example, reconstructed):

Use https://downdetector.com.au/ as an independent verification signal. Treat it as user-reported and indicative only. Always remind people to confirm in their own tenant’s Service health in the Microsoft 365 admin center.

Include the 24-hour charts in every update (example, reconstructed):

Every outage update should include Downdetector’s 24-hour report chart for each affected service, including Microsoft 365, Outlook, Teams and OneDrive when they are relevant.

Produce a copy-and-paste report for MSPs and admins (example, reconstructed):

For each update, give me a copy-and-paste summary report written for MSPs and administrators, including the Downdetector graphics if possible. I will send it on myself. Don’t email customers or post it to social media unless I ask.

Relay every Microsoft update, and flag a late one (example, reconstructed):

Relay every Microsoft status update, even minor ones. If Microsoft’s promised next update is more than 10 minutes overdue, send me a short overdue note even if the status text hasn’t changed.

Publish automatically to one WordPress page only (example, reconstructed):

Automatically publish each update to a single existing WordPress page: https://blog.ciaops.com/m365-outage-status/. I am giving standing approval for that one page only. Update that page and upload charts for it. Do not create a second page, do not change any other page, post or setting, and never touch any other site.

Add a plain-English section for non-technical readers

This is close to what I actually asked later in the day:

Can you add a new section to the report and WordPress page for non-technical people? There should be the Microsoft tech-speak as well as a plain-English end-user explanation of the issues and resolutions for the wider audience. Put the plain-English section first.

A tighter version you can reuse (example):

For each outage update, open both the copy-and-paste report and the WordPress page with a heading “In plain English (for everyday users)”. Cover what isn’t working, what still works, what staff should and shouldn’t do, and what Microsoft is doing, without jargon. Follow it with “Technical detail (for IT admins and MSPs)”.

Close an incident on your side

This is the wording I used at 10:39pm:

Consider this outage resolved.

If you want the bot to be more precise, use something like (example):

Consider this outage resolved on our side. Add a closing note to the WordPress page and the report. Do not claim that Microsoft has formally declared it restored unless they have. Keep watching for genuinely new incidents. If Microsoft keeps posting about this same incident, record those posts in the state file but don’t alert me or rewrite the page each time.

The closing note published at 10:41pm said CIAOPS had stopped tracking the incident, quoted Microsoft’s last 10:04pm update, and told people still seeing problems to check Service health or status.cloud.microsoft. It did not pretend Microsoft had closed EX1550543 / MO1550821.

A routine prompt you can adapt

A routine needs a saved prompt and a trigger. The trigger I use is a Sydney-time schedule, every 15 minutes: CRON_TZ=Australia/Sydney 7,22,37,52 * * * *, with a little flexibility either side. The prompt should describe intent, not a brittle list of tool names, because connectors change. Here is a generalised version of the watch we ended up with. It is an example, adapted from the behaviour of the running routine, not a verbatim paste of the saved text. Change the page URL and the approval wording to suit your own site.

You are checking for major Microsoft 365 outages.

1. Read the public Microsoft status feeds at https://status.cloud.microsoft/ (the Microsoft 365, Azure and Power Platform JSON endpoints). Ignore the standing Power Platform “Available” notice. Convert all times to Sydney time. 2. Compare what you find with the state file from the last run. Use the last updated time and the message body, not the id alone, to decide whether anything changed. 3. If a major incident is active, also check public posts from @MSFT365Status and the Downdetector Australia pages for Microsoft 365, Outlook, Teams and OneDrive. Capture the 24-hour report chart for each relevant service. Treat Downdetector as user-reported and indicative only. 4. If nothing material has changed, and Microsoft is not more than 10 minutes late for a promised update, do not message me. Just refresh the state file if needed. 5. If this is a new major incident, a change to an active one, a restoration, or an overdue Microsoft update, message me in this chat. Send a short summary first, then a copy-and-paste report. Put “In plain English (for everyday users)” first, then “Technical detail (for IT admins and MSPs)”. Attach the charts. 6. When there is a material change, update the single existing WordPress page I have approved for this purpose, and upload the new charts to that page. Do not create another page or change anything else on the site. After publishing, fetch the public page in a way that bypasses the cache and confirm the new “Last updated” line is actually visible. 7. If I have closed a particular incident, keep watching for new outages, but ignore further posts about the closed incident. Record them silently in the state file. After Microsoft marks it resolved, or 24 hours after I closed it if it is no longer listed, reset the public page to a short “No major Microsoft 365 outage” message. 8. Never send email, post to X, or contact customers as part of this watch. Never handle passwords or other secrets.

Message me in this chat only when there is something to report. If nothing has changed, stay quiet.

That last line is easy to skip and expensive to leave out. A 15-minute routine that congratulates itself four times an hour is not a watch. It is noise.

As the day went on I tightened and relaxed the rules in chat. When I wanted those changes to survive the next scheduled run, I made sure the saved routine itself was updated, rather than assuming a chat instruction would stick on its own.

Auto-publishing to a WordPress page

This is the part that makes the watch useful to other people, not just to me. During the outage, the same report that landed in my chat was also written to a public page, with the charts, in a consistent layout. Anyone I pointed at the URL could refresh that one link rather than wait for me to forward a message.

In the earlier watch post I said a routine should draft a customer notice and wait for approval, and should not update a status page on its own. That is still the right default. A bot that can publish to your blog is a bot that can publish the wrong thing, to the wrong place, at 2am.

What I did on 13 November was a scoped exception, not a change of that policy. I already had a published WordPress page with a stable slug, m365-outage-status, and a public URL I could share. Comments are closed. The title stays the same; only the body changes. The bot uses the WordPress.com connector for the CIAOPS blog. Writes of this kind normally ask for confirmation. I gave standing approval, in writing, for two actions only: updating that one existing page, and uploading new Downdetector charts destined for it.

That approval does not cover any other page, any blog post, menus, settings, or any other site. If you copy this, say the restriction out loud in the prompt and in the approval. “Publish it to my blog” is too wide. Ordinary CIAOPS articles still go through the normal draft-and-schedule process.

Create the page first. Do not ask the bot to invent a new post every time, and do not let it create a second status page if the first lookup fails. If the bot cannot find the page, it should stop and tell you, not improvise.

Keep a fixed layout. The page we used on 13 November had eight parts, in this order: a short intro; a Last updated line, in Sydney time, including the weekday and date; an H2 incident heading; an H3, In plain English (for everyday users); an H3, Technical detail (for IT admins and MSPs); the Downdetector Australia charts, each with a caption and a note that the data is user-reported; the sources; and a disclaimer that Downdetector is indicative only, and that people should confirm in their own tenant’s Service health. When I closed the incident, a short closing note went in under the H2, so no one had to hunt for it.

Upload fresh charts, and use the new media. Each run captures new charts and uploads them, then points the image blocks at the new media. Re-uploading the same filename can produce a new file in the library. Use the new id.

Review the page after every publish, because of cache. WordPress.com can briefly serve the previous version of the page. A run is not finished when the update call returns. Fetch the public URL in a cache-busted way, check that it returns a normal page, check that the new “Last updated” line is in the body, and check that the chart URLs actually return images. When I am at the desk I also glance at the public page in a browser. A successful write is not the same as a page a customer can actually read.

Reset the page after the incident, on a delay. Once Microsoft marks the incident resolved, or 24 hours after I closed it if it is no longer listed, reset the page to a short “No major Microsoft 365 outage” message. That keeps the URL stable for the next event.

The report format, with a short example

Every update I received had two parts: a short summary I could read on a phone, then a paste-ready report, starting with the everyday-user section. That was a late addition, and it was the right one. The mid-afternoon Microsoft updates were accurate, and almost unreadable if you just wanted to know whether you could send email or join a Teams meeting.

The plain-English section answers four questions: what is not working, what still works, what staff should and should not do, and what Microsoft is doing. The technical section carries the incident ids, the service list, the admin actions and the timeline.

Here is a shortened example, based on the 10:04pm update:

In plain English (for everyday users)

Since early Friday morning, many people have not been able to use Outlook email, calendars and some other Microsoft 365 features. Teams calls, meetings and chats mostly still work, and files in SharePoint and OneDrive still open. This is a problem at Microsoft’s end, not your computer or your account. Please don’t reset your password or reinstall anything, and only resend an email if you get a bounce. Microsoft is holding delayed messages for up to 48 hours. Its 10pm update said it had finished repair work on part of its Asia Pacific systems and was gradually sending traffic back. Email access and delayed delivery were improving, but some problems would still come and go. It had not given a time for a full recovery.

Technical detail (for IT admins and MSPs)

  • Status: service degradation, recovery in progress but not complete. Incident EX1550543 / MO1550821. Next Microsoft update due by 11:00pm AEDT.
  • Impact: Exchange Online mailbox access and delayed delivery; calendar features in Teams; Copilot experiences that need mail, calendar or files; plus impact on a range of admin and security portals that depend on the same path.
  • Admin actions: track the incident in Service health; do not reset passwords or rebuild profiles to “fix” it; do not ask senders to resend unless they get a bounce; expect users to restart Outlook or Teams once the service is stable.

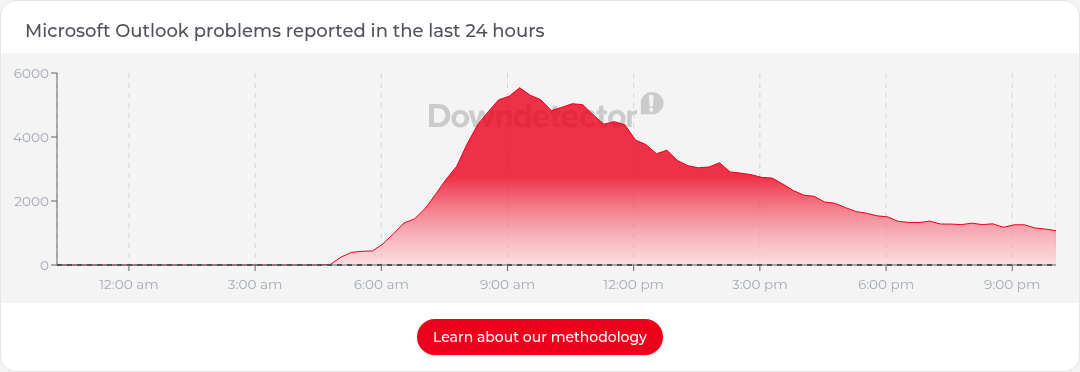
The charts sit under that. These two were captured from Downdetector Australia at 10:17pm AEDT on 13 November 2026. They are user-reported, and they were already well off the mid-morning peaks, which matched Microsoft’s “improving, but not finished” wording.

Downdetector Australia 24-hour chart of user reports for Microsoft 365, 13 November 2026, 10:17pm AEDT
Downdetector Australia 24-hour chart of user reports for Microsoft 365, 13 November 2026, 10:17pm AEDT. User-reported and indicative only.
Downdetector Australia 24-hour chart of user reports for Outlook, 13 November 2026, 10:17pm AEDT
Downdetector Australia 24-hour chart of user reports for Outlook, 13 November 2026, 10:17pm AEDT. User-reported and indicative only.

Guardrails, and what the day taught me

Standing approval covers one WordPress page and the chart uploads for that page. Everything else waits for me. The bot drafts; I send. It does not email customers, or post to X or Teams, on the back of an outage update. The watch uses public sources. It does not sign in to a tenant or handle passwords. Every report is in Sydney time, with the source named. Once I have closed an incident, repeat posts about it are recorded and not re-published. Downdetector is never treated as official.

Official status and independent signals can lag each other, and both can lag what users are feeling. Downdetector reports were climbing from about 5am. Microsoft’s first post was at 8:01am. Later, some X posts only repeated the status page, and one useful note appeared on X without a matching status-page change. You want all three sources, and you want the bot to say when they agree and when they do not.

Recovery is not a straight line. This incident had several moments that looked like progress and then went backwards, including servers that failed again under load and a mitigation that caused a surge of internal traffic. If you only relay “good news” updates, you will mislead people. Relay every official update, including the dull ones and the setbacks.

Promised update times slip. When the 7:30pm update did not arrive, a short overdue note was more useful than waiting politely. I would rather get a “Microsoft is late” message than discover an hour later that everyone else is waiting on the same missing post.

Write for two audiences or you will fail one of them. The technical report is for MSPs and admins. The people ringing the help desk need different sentences: what still works, don’t reset your password, don’t resend mail unless it bounces. Putting that section first made the public page usable without watering down the admin detail.

Decide when you are done, even if Microsoft is not. At 10:39pm I closed it on the CIAOPS side because I no longer needed a live running commentary. The page said that in so many words. The routine kept watching for the next incident. And build this before you need it. I added sources, charts, the public page and the plain-English section during the outage. It worked, but it was harder than it needed to be.

The same bot as a help desk, including AnyDesk

The outage watch sits on the bot I already use for remote IT support. That is a different job, and it has a different trigger.

Customers can email a dedicated help desk inbox. An email-triggered routine reads the thread, treats the email as untrusted data, and follows no instructions in it except to pick up an AnyDesk address the customer has sent for that request. On a new request, it replies once in that thread, as me, with thanks and setup instructions: download AnyDesk from the official site, run it (no install needed), reply with the address shown in the app and a short description of the problem, keep AnyDesk open, and click Accept when the connection request appears.

When the customer replies with an AnyDesk address, the bot starts a session from its computer and tries to fix the problem. A few rules are non-negotiable:

  • It only connects to an address I have given it, or that a customer I have arranged has sent to that help desk inbox. It must not connect to an address from any other source.
  • The remote user has to click Accept.
  • It can look around and diagnose freely, but it has to ask me before anything consequential: installing or uninstalling software, deleting files or data, changing security settings, registry edits, restarts, signing the user out, or anything that could lose work.
  • It never types, reads out or reveals passwords or other secrets. The remote user enters credentials and MFA themselves.
  • When it is finished, it closes the connection and tells me who wrote, what it replied, what it found, what it changed, and anything left to do. Times are in Sydney time.

The two ideas fit together on an outage day. The watch tells you it is a Microsoft-side incident, and gives you something you can send to users. The help desk inbox is how those users reach you if their device still needs a look. The same guardrails apply: no secrets, no unsolicited connections, and no consequential changes without asking.

A URL you can keep, and a watch you can copy

The public page is here: https://blog.ciaops.com/m365-outage-status/. When there is no major incident, it will go back to a short “no major outage” message and keep that address.

Official Service health in the admin center remains the first place to look for your tenant. A bot does not replace that, and it does not replace a phone call to a worried customer. What it can do is watch the public sources, keep your times straight, and keep one honest page up to date while you get on with the rest of the day.

If you want to try the same approach, start with the first prompt in this post, put it on a 15-minute routine, and only then add X, Downdetector, the report format and a single, tightly approved web page. Set the guardrails before the next Friday morning, not during it.

Coping With Change Is the New Competitive Advantage

A calm business owner stands still in a busy office while colleagues rush past in a blur

I used to think the measure of a good business was what it knew. Its products, its processes, the expertise its people had built over years. Those still matter. But I’m increasingly convinced the real measure of future success is something else entirely: how well you cope when everything you know keeps shifting under your feet.

And here’s the uncomfortable part. Not everyone has the skills to do that.

Change isn’t an event anymore

We used to treat change as a project. A migration, a new system, a restructure. You pushed through it, things settled, and you went back to normal. That rhythm is gone. Microsoft 365 alone changes every week. Copilot picks up new capabilities, agents arrive, settings move, licences get reshuffled. Then there’s everything happening outside your tenant.

This isn’t just my gut feel. The World Economic Forum’s Future of Jobs Report 2025 found that nearly 40% of skills required on the job are set to change, and that 63% of employers see the skills gap as the key barrier to transforming their business. It also notes that human skills like resilience, flexibility and agility will remain critical alongside technical ones.

Read that again. Resilience and flexibility are being named next to AI and cybersecurity. Coping with change is now a core skill.

Why some people thrive and others stall

Picture two people in the same team when Copilot lands in Teams and Outlook. One pokes at it, gets a few things wrong, adjusts and within a month has quietly rebuilt how she runs her week. The other waits for training, waits for someone to tell him the rules, and eventually decides it isn’t for him. Same tools, same opportunity, very different futures.

The difference usually isn’t intelligence. It’s comfort with not knowing. Some people find uncertainty interesting. Others find it threatening. I don’t blame the second group. Many were rewarded for years for knowing the answer, not for working one out.

I wrote recently about this gap in Same Licence, Different Results. The licence is identical. What people bring to it is not.

Owners set the pace

If you own a business or an MSP, this lands on you first. Your team takes its cue from how you handle change. If every new thing is met with a sigh and a “we’ll look at it later”, that becomes the culture. If you visibly try things, admit what didn’t work and share what did, that becomes the culture instead.

A few things I’d focus on:

  • Make experimenting normal. Give people time to play with Copilot on real work, not just in a training session.
  • Shrink the cost of being wrong. Small trials in a pilot group beat big bets made once a year.
  • Teach how to learn, not just what to click. The buttons will move. The habit of figuring things out won’t.
  • Notice who is struggling. Some people need more support through change, and that’s fine. Leaving them behind isn’t.

For MSPs there’s an opportunity here too. Your customers don’t just need the technology deployed. They need help absorbing a constant stream of change. That’s a service, and a valuable one.

The skill underneath the skills

I don’t think the winners over the next few years will be the people who know the most about AI today. Today’s knowledge has a short shelf life. The winners will be the workers, owners and businesses who can keep re-learning without falling apart each time the ground moves.

That’s a skill. It can be built. But only if we admit it’s missing and start practising it on purpose.

We have a new LLM in Copilot winner: Opus 5.5 edges Fable 5.2

Two colleagues comparing printed reports at a desk at dusk, teal and amber light on blank pages

A while back I compared the different LLMs in Copilot, and Fable 5.1 took the honours in Cowork:

https://blog.ciaops.com/2026/09/02/we-have-a-new-llm-in-copilot-winner/

GPT 6 Astra later took the trophy, and I then ran Opus 5.5 against it:

https://blog.ciaops.com/2026/09/17/astra-takes-the-trophy/

https://blog.ciaops.com/2026/09/23/i-think-we-need-a-count-back/

I have now put the latest LLM in Copilot through the same prompt in Cowork, judged again by Grok. First I compared Fable 5.2 with the September Fable 5.1 report. The results are here:

https://github.com/directorcia/general/blob/master/Copilot/Comparisons/20261113-Cowork-Fable-51-52-Grok-eval.md

and Fable 5.2 (Cowork) is ahead, 8.7 to 8.1. It was stronger on argument, evidence and presentation. Depth was roughly even.

I then put that November Fable 5.2 report against Opus 5.5. That evaluation is here:

https://github.com/directorcia/general/blob/master/Copilot/Comparisons/20261113-Cowork-Fable52-Opus55-Grok-eval.md

and the winner of that head-to-head is now:

Opus 5.5 (Cowork)

The scores are close: 8.9 against 8.6. Argument was a tie at 9.0 each. Opus 5.5 was stronger on evidence (9.2 vs 8.3) and detail (9.3 vs 8.4). Fable 5.2 was the more polished, executive-friendly read (9.0 vs 8.0). Both reports reach much the same strategic conclusions. The gap is in how tightly the evidence is handled, not in a different industry story. Opus 5.5’s research cut-off was earlier (23 September against 11 November), so Fable 5.2 had some later data and still came second.

You can see the Fable 5.2 output here:

https://github.com/directorcia/general/blob/master/Copilot/Comparisons/20260816/20261113-Cowork-Fable52.docx

and the Opus 5.5 output here:

https://github.com/directorcia/general/blob/master/Copilot/Comparisons/20260816/20260923-Cowork-Opus55.docx

along with the other outputs:

https://github.com/directorcia/general/tree/master/Copilot/Comparisons/20260816

These two evaluations don’t include credit costs, so I am not going to invent a new price list. They also don’t re-run Astra, so this is not a new overall series winner. For this latest LLM in Copilot pairing, though, Opus 5.5 edges Fable 5.2, after Fable 5.2 had already improved on Fable 5.1.

As soon as the next model turns up in Cowork, I’ll test it and update this information.

How to Set Up a PowerShell Bot in Grok Bot as a Shared Tool

Two colleagues reviewing a laptop in a quietly lit office, teal and amber light on a blank screen

Most MSPs already have a folder of PowerShell scripts that do the real work: connect to a tenant, check a setting, produce a report. The awkward part is not writing the next script. It is getting a consistent, least-privilege way to run the ones you already trust, without giving every assistant in your toolkit its own path into Microsoft 365.

I keep a dedicated PowerShell bot in Grok Bot for this. It is not there to chat about PowerShell in general. It is a tool. When a security monitor, or my Chief of Staff, needs a script run, they ask that bot to do the job and report back. The rest of my bots stay out of the tenant.

That sounds simple, and once it is set up it is. The work is in giving the bot a clear job, pointing it at a script repository, and letting it sign in with a certificate so later runs can go without a prompt. I will walk through that setup, then use the Microsoft Defender for Office 365 Recommended Configuration Analyzer (ORCA) as the worked example.

Why a dedicated PowerShell bot

If every bot can run scripts, every bot needs tenant access, and every bot can make a change. I would rather have one specialist with a tight set of rules: use the scripts in the repo before writing anything from scratch, stay read-only unless I say otherwise, ask before anything that changes a tenant, and report back in plain English.

Other bots can then call it when they need it. That is not a theory. A marketing bot has asked mine for a read-only inventory of a script repo. A chief-of-staff bot has sent it backup and investigation jobs. The PowerShell bot does the work and replies. I wrote earlier about using a specialist bot to investigate a worrying mailbox change. This is the same idea, pointed at scripts.

1. Create the bot and give it a clear role

You can do this in chat. The only app locations I will point you to are ones I have verified: the per-agent info pane, and Settings if you need to check the timezone later.

Click the agent’s name in the chat header, or use Cmd+Shift+I, to open the per-agent info pane. The gear beside the X opens the per-agent settings for avatar, name, title and description. Call it PowerShell, or whatever name you will use when another bot refers to it, and give it a description that states the job.

You can also set the role in chat:

Set this bot’s name to PowerShell and set the description to: You are a specialist PowerShell tool for an Australian MSP. Other bots will ask you to run scripts and report back. Prefer scripts from my GitHub repositories, and pull the latest copy before you run one. Run scripts on your computer. Use certificate-based app-only sign-in for unattended Microsoft 365 work. Stay read-only unless I clearly ask for a change. Before anything that changes a tenant, tell me exactly what you will do and wait for approval in this chat. Do not invent a script if a repo already has one that fits. Report results in plain English, and say what you could not do.

Save the same rules as a standing instruction in the first conversation. Be explicit that relayed approvals from another bot do not count for tenant changes. That is a rule I have had to enforce, and it is the right one.

2. Point it at a GitHub repo

A PowerShell bot without a script library will invent helpers. I would rather it used the scripts I already maintain. Mine lives at https://github.com/directorcia/Office365. Tell the bot that in chat:

Add https://github.com/directorcia/Office365 to your list of script sources. When a job needs a script, check that repo first, pull the latest copy, and run it from there if it fits. Do not write a new script if one in the repo already does the job. Do not commit or push anything unless I ask.

That repo is public, so the bot can clone and pull it on its own computer without a token. If you also have a private repo, the safest approach I have used is a fine-grained GitHub token limited to that one repository, with Contents set to Read-only. GitHub turns on Metadata read-only by itself. Leave every other permission at No access. The token is for clone and pull only, and it should not be stored in the repo.

I am not going to invent a GitHub settings screen in the Grok Bot app. I set this up in chat, then confirmed the bot could see the repo on its computer. Before each run, I expect it to pull the latest copy.

The Office365 repo includes the Linux certificate connect scripts I use for headless Exchange Online and SharePoint. I wrote about those in New scripts: Headless SharePoint and Exchange Online connections on Linux, built for agents. For Exchange, the script is o365-connect-exo-cert-linux.ps1.

3. Give it a headless way to sign in

Interactive sign-in is fine for a one-off on your own PC. It is a poor fit for a bot. Nobody is sitting at the bot’s computer to complete a browser prompt, and a prompt that nobody can answer will just hang. Certificate-based, app-only sign-in is the unattended path Microsoft documents for Exchange Online PowerShell.

The pattern I use is:

  • Generate the certificate on the bot’s computer, so the private key never leaves that machine.
  • Upload the public certificate to an app registration in Microsoft Entra ID.
  • Grant the Exchange.ManageAsApp application permission, with admin consent.
  • Assign a role that matches the work. For a read-only assessment such as ORCA, that is Global Reader or the Exchange View-Only Organization Management role group, not a full administrator role.

The connect script can also provision the Entra app. Read what it will assign before you use that option. A provision step that grants a broad Exchange role is the wrong default for a bot that mostly reads a tenant. I would rather start with a view-only role and add more later, with a human still in charge of the grant.

The first time, you will need to sign in once with a device code so the app can be created and consent can be granted. After that, the bot should connect with the saved profile and the unattended switch. On the Linux script, that is -UseCertificateAuth with -Headless (an alias of -noprompt):

./o365-connect-exo-cert-linux.ps1 -UseCertificateAuth -ProfileName YourProfile -Headless

Keep the PFX password out of the repo and out of chat prompts. The script will take it from a secret or from an environment variable you inject. Each command on the bot’s computer can start a fresh PowerShell process, so either reconnect each time or keep a session open per tenant. A different tenant needs its own connection.

4. Let other bots call it

This is the point of the setup. You do not want your news bot, or your security monitor, running Exchange cmdlets itself. You want it to ask the PowerShell bot.

I do not have a separate settings page I can point you to for that. What I can verify is simpler. You ask the other bot, in its own chat, to send the job to the PowerShell bot and report back. In a group chat, the per-agent info pane – the same one you open from the agent name in the header, or with Cmd+Shift+I – includes Members, and you can @mention a bot by name.

Here is the kind of prompt I would give a security monitor or a chief-of-staff bot:

Ask the PowerShell bot to run ORCA read-only against the tenant I name, using the Exchange certificate connection. It should install or update the ORCA module if needed, generate the report, summarise the results in plain English, and send back the HTML report. It must not change anything in the tenant. If it hits a permission gap, it should say so and stop, without granting itself extra access.

The PowerShell bot then does the work and replies. Keep change control in its own chat. If another bot relays “Robert said yes”, that is not the same as you typing the approval where the script will run.

You can also put a recurring check on the calling bot, not on the PowerShell bot. A routine lives in that bot’s per-agent info pane, under the computer preview. Check the timezone under Settings, on the General tab, opened from the sidebar account button at the bottom-left, or with Cmd+,. Routines usually start within a few minutes either side of the time you set. If the run must start right on the minute, say “exactly” or “sharp”. The routine prompt can simply tell the monitor to ask the PowerShell bot for this week’s ORCA report.

5. A worked example: running ORCA

ORCA is a PowerShell module that compares your Exchange Online Protection and Microsoft Defender for Office 365 settings with Microsoft’s recommended Standard and Strict values. Microsoft documents it alongside the recommended threat policy settings: you install the module from the PowerShell Gallery, connect to Exchange Online, and run Get-ORCAReport. It produces an HTML assessment of anti-spam, anti-phishing, Safe Links, Safe Attachments and related controls.

You also need the Exchange Online Management module. To run ORCA, the official project says you need the Exchange Online View-Only Configuration role. In practice that means a read-only role such as Global Reader or View-Only Organization Management, which is exactly the access I already wanted the bot to have.

Microsoft also has a configuration analyzer in the Defender portal. That remains the better long-term check, because the current gallery release of the ORCA module, 2.8.1, was last updated in December 2023. For an MSP, the value of running it from a bot is speed and repeatability, not that it replaces the portal.

Once the PowerShell bot exists, the request is short:

Run https://github.com/cammurray/orca against [tenant] read-only. Use the Exchange certificate connection. Install the ORCA module if it isn’t already there, run Get-ORCAReport, summarise the findings in plain English, and give me the HTML report. Do not change anything in the tenant.

That is close to the prompt I actually used. The bot connected with the certificate, ran the module, and sent the report back. In one tenant it finished in about five minutes, and it only read the tenant. Of 67 checks, 50 were OK, 5 were informational and 12 were recommendations. In another tenant the pattern was similar: 50 OK, 4 informational and 13 recommendations. Typical findings were anti-phish actions left at NoAction, a low phishing threshold, Safe Links allowing click-through or missing coverage on some domains, and outbound spam limits that did not match the recommended values.

Two caveats are worth knowing if the bot’s computer is Linux, which mine is. The DKIM and SPF checks use Resolve-DnsName, which is a Windows cmdlet, so those checks may not run. In one run a Safety Tips check also failed with a server-side error, and a protection alerts check was skipped because it does not work over a certificate sign-in. None of that is a reason to avoid the report. It is a reason to read the gaps as well as the recommendations.

The point is the effort on my side. I did not install modules by hand, hunt for the right connect script, or click through a report wizard. I asked the bot I already had, and it used the repo and the certificate I had already set up.

Sample prompts

These are the prompts I would start with if you are setting up the same pattern.

Create the bot:

Set this bot’s name to PowerShell and set the description to: You are a specialist PowerShell tool for an Australian MSP. Other bots will ask you to run scripts and report back. Prefer scripts from https://github.com/directorcia/Office365, and pull the latest copy before you run one. Run scripts on your computer. Use certificate-based app-only sign-in for unattended Microsoft 365 work. Stay read-only unless I clearly ask for a change. Before anything that changes a tenant, tell me exactly what you will do and wait for approval in this chat. Report results in plain English, and say what you could not do.

Add the repo:

Add https://github.com/directorcia/Office365 to your list of script sources. When a job needs a script, check that repo first, pull the latest copy, and run it from there if it fits. Do not commit or push anything unless I ask.

The prompt another bot sends to call it:

Ask the PowerShell bot to run ORCA read-only against the tenant I name, using the Exchange certificate connection. Summarise the results in plain English and send back the HTML report. Change nothing in the tenant. If you hit a permission gap, say so and stop.

The ORCA run itself:

Run ORCA read-only against [tenant]. Connect with o365-connect-exo-cert-linux.ps1 using the saved profile and -Headless, then run Get-ORCAReport. Summarise the OK, informational and recommendation counts, list the important recommendations, and attach the HTML report. Tell me if any checks could not run, including DNS checks on Linux. Do not change anything in the tenant.

What I took from it

The useful design is not “give every bot PowerShell”. It is one specialist, a repo of scripts you already trust, and a sign-in that can run unattended without handing out a full administrator role.

Keep the human in charge of anything that changes a tenant, and keep that approval in the PowerShell bot’s own chat. Use official documentation when you check what a module is supposed to do – the Microsoft Learn connector is the straightforward way to pull that wording. And start with a real job, not a tour of features. For me, that job was ORCA. Once the bot was in place, running it was a short request, a few minutes of read-only work, and a report I could act on.

It’s Not the Model Anymore, It’s the Harness

An IT consultant at a desk surrounded by glowing connections linking a central light to many devices

For the last couple of years, most AI conversations I’ve had started the same way. Which model is best? Which one is smartest this month? Who just topped the leaderboard? I get why. The models were the shiny part. But I’m noticing the question changing, and I think it’s the right change.

The model is becoming the engine. What actually decides whether AI is useful in your business is everything bolted around it: the harness, the tools, the data it can reach and the rules it works within.

The engine isn’t the car

A brilliant model sitting on its own knows a lot about the world and nothing about your business. It can’t see your customer list, your contracts or yesterday’s Teams meeting. It can’t raise a ticket, update a Planner task or check a device in Intune. Without connections, it’s a very well-read stranger.

Microsoft 365 Copilot is a good example of where the value really sits. Microsoft describes Copilot experiences as differing by data grounding, integration depth and licensing, with work grounding coming through Microsoft Graph. Notice what that list doesn’t lead with. It’s not the model. It’s what the model is plugged into.

Picture two businesses using the same underlying model. One just chats with it. The other has it grounded in SharePoint, connected to their line-of-business system and able to run a Power Automate flow. Same brain, wildly different outcomes.

Tools are the new skills

This is why I’m paying so much attention to the Model Context Protocol. MCP is an open-source standard for connecting AI applications to external systems. In plain terms, it’s a common plug. Build a connector once and many AI tools can use it.

Microsoft has already brought it into Copilot Studio, where you can extend an agent with tools using MCP. That changes how I think about building agents. The hard work is no longer picking a model. It’s deciding which tools an agent gets, what data it can see, and what it’s allowed to do with them.

I touched on a version of this when I wrote Why developers don’t own this one. The value of an AI tool at the command line came from what it could reach and run, not from the model’s raw IQ.

What this means for MSPs

If you run an MSP, this is good news. Model choice is turning into a commodity decision that vendors will keep changing underneath you. The harness is where your expertise lives. That’s the bit you can design, secure and support.

Here’s where I’d focus:

  • Grounding: is the data Copilot reaches current, permissioned properly and worth trusting?
  • Connectors: which systems should an agent touch, and which should it never see?
  • Guardrails: what can an agent read versus actually change, and who approves the risky steps?
  • Identity and audit: can you tell, through Entra and Purview, what an agent did and on whose behalf?

That last point matters. Every new tool you connect is also a new door. Exposed or poorly authenticated MCP servers have already shown up in security research I covered in the CIA Brief 20260516. A great harness is a secure harness.

Stop asking which model

I’m not saying models don’t matter. Better reasoning helps. But the gap between good models is shrinking, while the gap between a well-connected agent and a lonely chatbot is enormous.

So next time someone asks me which AI is best, I’ll answer with a question. Best at what, connected to what, and trusted to do what? Get those answers right and the model almost picks itself.

How Grok Bot Simplifies Security Checks and Investigations

A professional reviewing a laptop in a dim office, with teal and amber lighting

A Full Access grant on a mailbox is the kind of audit event that makes you sit up. Someone, or something, has just been given the right to open a mailbox and read what is in it. In an MSP or SMB tenant that is not a change you ignore. It is also, as I was reminded this week, the kind of change Microsoft’s own Exchange service can generate as routine maintenance. The hard part is telling those two things apart quickly, without handing extra privilege to the tool that is helping you look.

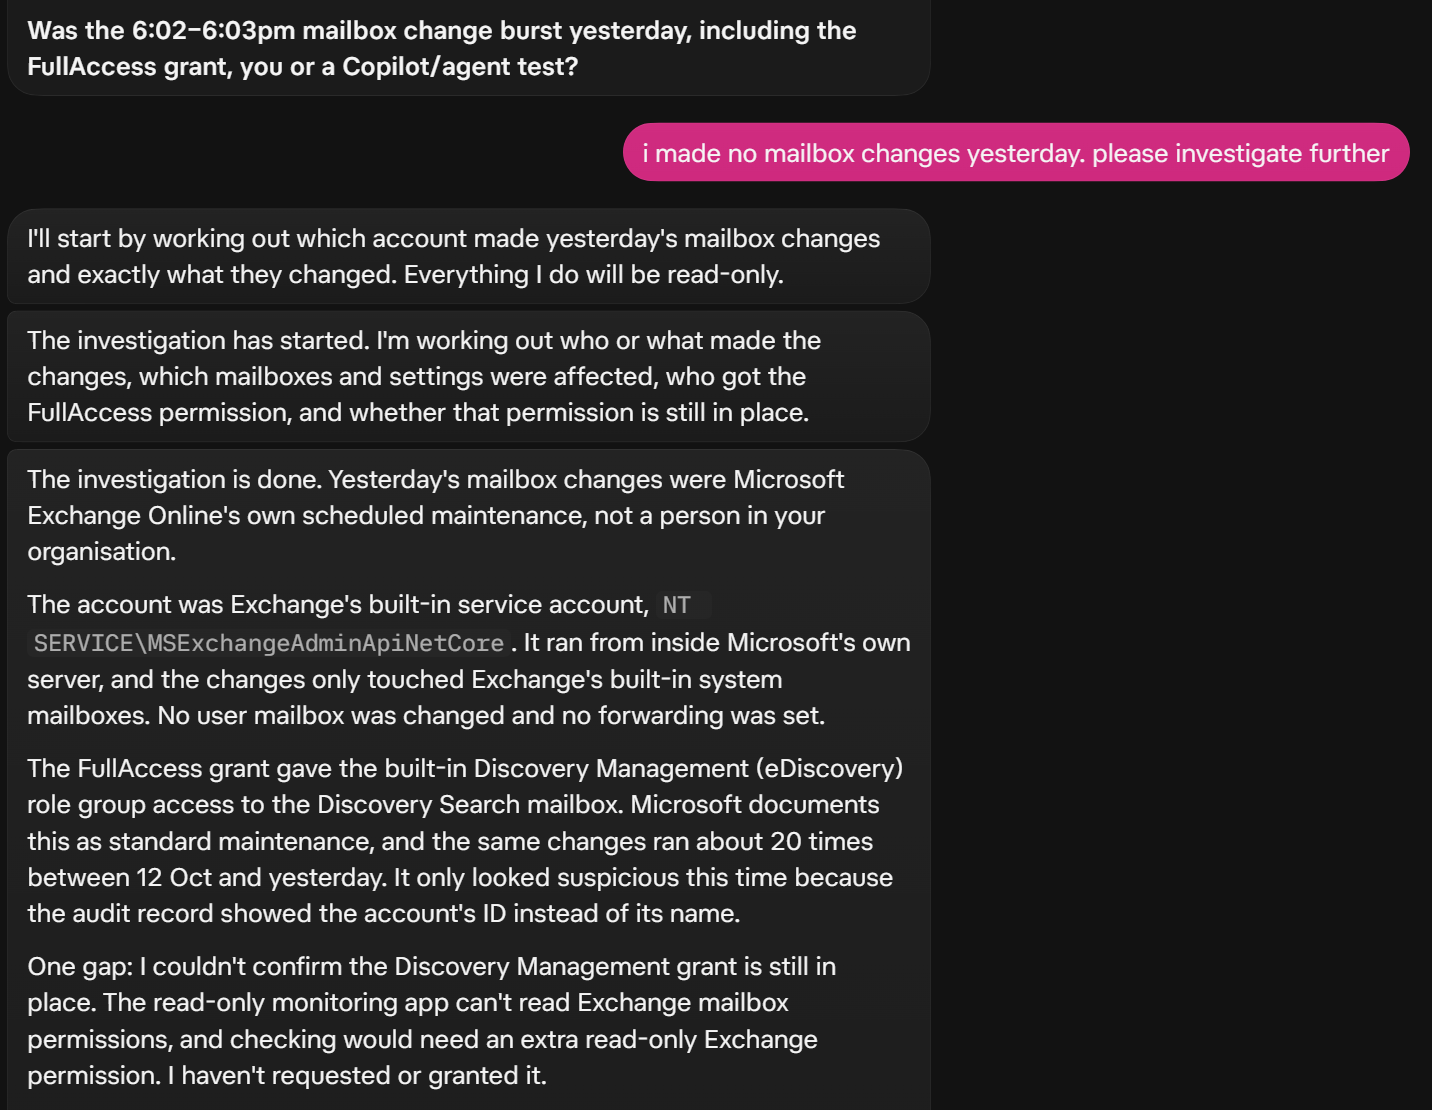
My read-only Microsoft 365 monitoring bot flagged a burst of mailbox changes at 6:02–6:03pm the previous evening, including a Full Access grant. It did not assume the worst, and it did not start changing anything in the tenant. It asked me a straight question: was that burst me, or a Copilot or agent test?

I had not made any mailbox changes. I told it to investigate further. What follows is how that investigation ran, what the issue turned out to be, and how you can set up a similar read-only check of your own.

Why audit noise is hard to work with

The Microsoft Purview unified audit log is one of the most useful tools in a Microsoft 365 tenant. It is also one of the noisiest. A genuine mailbox permission change sits in the same log as scheduled Microsoft maintenance, directory sync, and admin work you already know about. The record is often technically correct and still hard to read at a glance.

That problem is sharper for MSPs and smaller IT teams. An MSP is watching this pattern across many tenants, usually without a 24-hour security operations centre. An SMB often has one or two people who also run the rest of the environment. In both cases the failure modes are the same. You either spend the evening chasing a change that Microsoft already documented as normal, or you scroll past something that deserved a closer look.

Alerts do not solve this by themselves. An alert can tell you that a Full Access grant happened. It cannot tell you whether the actor was a person, an app you own, or Exchange doing maintenance. It also cannot tell you, in plain English, what was touched and what was not.

I already use Grok Bot for a morning brief of MSP news and security updates. That is a different job. Industry news will not investigate a change inside your tenant. For that, you need a bot with read-only access, a habit of asking you first, and a willingness to stop when it cannot see enough.

How Grok Bot helps

The value is not that the bot is cleverer than the audit log. The log already has the events. The value is the way the work is done:

  • It monitors in read-only mode, so a routine check cannot become a change in the tenant.
  • It asks the human first when something looks unusual, instead of guessing or firing a ticket.
  • It investigates on request, then reports findings in plain English.
  • It states gaps honestly. If it cannot confirm a permission is still in place, it says so, rather than quietly requesting more access for itself.
  • When more access is genuinely needed, the human grants it, after the bot has explained what it needs and what the trade-offs are.
  • It can pause for a safety check, including whether you are looking at the right tenant.

That last point matters more than it sounds. A useful investigation bot is sceptical, not eager.

A real investigation

The bot’s first message was the right one. It had seen a burst of mailbox changes at 6:02–6:03pm, including a Full Access grant, and it wanted to know whether that was me or a test.

Screenshot of a Grok Bot chat. The bot asks whether the 6:02–6:03pm mailbox change burst, including the FullAccess grant, was the author or a Copilot or agent test. The author replies that they made no mailbox changes and asks the bot to investigate further. The bot reports, read-only, that the changes were Exchange Online scheduled maintenance by the built-in NT SERVICE\MSExchangeAdminApiNetCore account on system mailboxes only, with a FullAccess grant to Discovery Management on the Discovery Search mailbox, and notes it could not yet confirm the grant is still in place.
My monitoring bot asked whether the mailbox change burst was me, then investigated read-only when I said it wasn’t.

I replied that I had made no mailbox changes the previous day, and asked it to investigate further.

It stayed read-only. The actor was not a user, and it was not one of my apps. It was Exchange’s built-in service account, NT SERVICE\MSExchangeAdminApiNetCore, running from inside Microsoft’s own servers. It had only touched Exchange’s built-in system mailboxes. No user mailbox was changed, and no forwarding was set.

The Full Access grant was also narrower than it first appeared. It gave the built-in Discovery Management role group access to the Discovery Search mailbox. That is Exchange’s eDiscovery role group, and Microsoft documents this permission as the default. The same pattern had already run about 20 times between 12 October and the day of the alert. It only looked suspicious because the audit record showed the account’s identifier rather than its name.

That reading matches Microsoft’s own documentation. In the audit log activities guidance, Microsoft says you may see NT SERVICE\MSExchangeAdminApiNetCore on mailbox permission events, that this is a system account in the Exchange service in the Microsoft cloud, and that a common audited activity is updating permissions on the Discovery Search mailbox to verify that Full Access — “which is the default” — is assigned to Discovery Management. If you want to check that kind of claim while you investigate, the Microsoft Learn connector in Grok Bot is the straightforward way to pull the official wording rather than relying on memory.

So the story in the audit log was already pointing to routine maintenance. There was still a gap.

Closing the last gap

The bot was honest about what it could not do. It could see the audit events, but the read-only app could not read current Exchange mailbox permissions, so it could not confirm the Full Access grant was still in place. It did not request extra permission for itself, and it did not grant itself any.

Instead, it explained the access it needed, and I granted it. That was the Exchange.ManageAsApp application permission, with admin consent, plus the Global Reader role.

This is where least privilege deserves a proper look. Exchange.ManageAsApp lets an app connect to Exchange Online PowerShell without a user sign-in, but it is not a blank cheque. Microsoft still requires an Entra role or an Exchange role group to decide what the app is allowed to do. Global Reader is a supported choice for that, and Microsoft describes it as the read-only counterpart to Global Administrator: it can read settings and administrative information across Microsoft 365 services, but it cannot take management actions.

It is still broader than this particular check required. In Exchange Online, Global Reader maps to the View-Only Organization Management role group, whose members can view the properties of any object in the organisation. If all you need is Exchange visibility, adding the app to View-Only Organization Management is the narrower path. Global Reader also grants read access across other Microsoft 365 admin centres. The bot pointed that alternative out. I chose Global Reader anyway, because I wanted the broader read-only view for this monitoring bot and I was the person granting it. The trade-off was explicit. That is the standard I want: the human decides, with the narrower option on the table.

There was one more useful pause. I sent a screenshot from the admin portal so the bot could see the consent and role grant. The header showed a name that made it stop and warn me I might be in the wrong tenant. It was actually this tenant’s display name. I would rather a bot hesitate over a familiar name than charge ahead in the wrong directory.

With the access in place, the bot connected app-only to Exchange Online PowerShell, ran only Get-* read cmdlets, and disconnected. It confirmed that Discovery Management still has Full Access on the Discovery Search mailbox. The permission is not inherited, and it is not a deny entry. That matches Microsoft’s documented default, and it was still in place after the maintenance. Nothing in the tenant was changed. The evidence was written to an investigation file with no secrets in it.

The outcome was straightforward: routine Exchange Online maintenance, no incident. It was all resolved the next morning, within minutes of the access being granted.

Example prompts

These are the kinds of prompts I would start with if you want the same behaviour.

Set the bot’s role:

You are a read-only Microsoft 365 security monitoring bot for an MSP. Watch the unified audit log for unusual mailbox permission changes, forwarding, and similar high-impact events. When you see something that looks unusual, ask me whether it was expected before you investigate. Stay read-only. If you hit a permission gap, tell me what you cannot see and what access would close that gap. Do not request or grant yourself extra permission.

Create a recurring check:

Create a routine called Mailbox permission watch. Every weekday at 8:15am Sydney time, search the unified audit log for mailbox permission changes since the last run, including Full Access grants and forwarding changes. If nothing material happened, tell me that in this chat and stop. If something looks unusual, summarise it in plain English and ask me whether it was expected before investigating further. Stay read-only.

When an alert appears:

I made no mailbox changes yesterday. Please investigate further. Stay read-only. Identify the actor, what was changed, whether any user mailbox was touched, and whether forwarding was set. If the actor looks like a Microsoft system account, check the official Microsoft documentation and tell me if this is a known maintenance pattern. If you cannot confirm the current permissions, say so clearly and do not try to expand your own access.

After you have granted extra read access:

I have granted the access we discussed. Connect app-only to Exchange Online PowerShell, run only Get-* cmdlets, confirm whether the permission is still in place, then disconnect. Record the findings in an investigation file with no secrets. Change nothing in the tenant.

How to set up a similar read-only check

You can do most of this in chat. The only app locations I will point you to are ones I have verified: the per-agent info pane, and Settings for timezone.

1. Give a bot a clear role

Use a dedicated bot for tenant monitoring, so investigation work is not mixed with unrelated chats. Click the agent’s name in the chat header, or use Cmd+Shift+I, to open the per-agent info pane. The gear beside the X opens the per-agent settings for avatar, name, title and description. Give it a clear description: read-only monitoring, ask first, investigate on request, state gaps honestly, never escalate its own permissions.

2. Start with read-only audit access

Give that bot read-only access to the unified audit log through an app you control. Start with enough access to search the log, and nothing more. The investigation above got a long way on audit events alone.

3. Save the behaviour in chat

Use the role prompt above. Be explicit that the bot must ask you before digging in, must stay read-only, and must not request or grant itself extra permission.

4. Add Microsoft Learn for official checks

Add the Microsoft Learn connector if you want official documentation checked during an investigation, rather than after the fact. I walked through that setup in How to Set Up MCP Connectors in Grok Bot with Microsoft Learn.

5. Create a routine

Create the routine in chat. You can review saved routines in the same per-agent info pane, under the computer preview. Check the timezone under Settings, on the General tab, opened from the sidebar account button at the bottom-left, or with Cmd+,. Routines usually start within a few minutes either side of the time you set. If the run must start right on the minute, say “exactly” or “sharp”.

6. Grant extra access yourself when a gap appears

For a current mailbox permission check, that means Exchange.ManageAsApp with admin consent, plus a view-only role. Prefer View-Only Organization Management if you only need Exchange visibility. Use Global Reader only if you have a reason for the broader Microsoft 365 read access, and make that choice deliberately.

7. Keep an investigation trail

A file of findings with no secrets in it is more useful the next time the same maintenance burst appears.

What I took from it

The first lesson is the oldest one in this kind of work: verify before you panic. A Full Access grant is worth taking seriously. In this case it was Microsoft putting a documented default back where it already belonged. The audit log looked worrying because it showed an identifier instead of a familiar name. That is not a reason to ignore the alert. It is a reason to investigate it properly.

The second is least privilege. The bot did not help itself to more access when it ran out of visibility. I granted the extra permission, and I accepted a broader role than the narrowest option on the table. I am comfortable with that choice. I would not have been comfortable if the tool had made it for me.

The third is to keep the human in charge. The useful pattern was simple. The bot watched, asked, investigated, admitted a gap, explained the access it needed, paused when a screenshot might have been the wrong tenant, ran only read commands, and wrote down what it found. I still made the calls that mattered.

That is what simplified the security check. Not a dashboard, and not a promise that every alert is harmless. I went from a worrying Full Access grant to a documented, no-incident conclusion the next morning, without the tool quietly expanding its own reach. For an MSP, that is the difference between an audit event that ruins the start of the day and one that has already been explained.